• Open

    Managing Amazon Bedrock costs end to end: A playbook for FinOps and platform teams
    This post presents a five-stage operating model for managing Amazon Bedrock cost: attribute every dollar to an owner, make every request observable, enforce budgets, optimize platform defaults, and operate a review cadence. Written for FinOps and platform engineering teams.  ( 152 min )
    Preview web apps live as your coding agent builds them with Amazon Bedrock AgentCore runtime
    Amazon Bedrock AgentCore Session endpoints give each runtime session an authenticated URL that forwards any HTTP method, path, and WebSocket connection to the ports you allow. In this post, you deploy a coding agent that keeps a Vite website running in its session, then watch the live site update in your browser as the agent edits files.  ( 150 min )
    How Worldwide Express automated freight exceptions with Amazon Bedrock
    Worldwide Express automated its less-than-truckload freight billing-exception process with a multi-agent solution built on Amazon Bedrock. Six months after launch, the company cut active exceptions by 75%, improved time-to-cash by four weeks, and unlocked $10 million in free cash flow.  ( 146 min )
    Configure the ChatGPT desktop app with Amazon Bedrock in AWS GovCloud (US)
    The ChatGPT desktop app is now available on Amazon Bedrock in AWS GovCloud (US). This post walks through a controlled local deployment that routes model inference to Amazon Bedrock in AWS GovCloud (US-West) using API-mode sign-in, a managed device policy, a named AWS profile, and network restrictions, so a security team can validate it before broader use.  ( 147 min )

  • Open

    How the UK Amazon Quick User Group grew in 2026
    The UK Amazon Quick User Group's 2026 roundup: three quarterly meetups, 150+ attendees, and customer stories from Arriva, Carsa, and Propulse Lab on using agentic AI and Amazon Quick to turn data into faster decisions, higher satisfaction, and scalable growth.  ( 148 min )
    Building intent-driven UI testing with Amazon Nova Act
    Epsilon's Agentic Platform team delivers UI testing as a managed, multi-tenant service built on Amazon Nova Act and Amazon Bedrock AgentCore Browser Tool. Tests are written in plain English and run on browsers managed by AWS, giving every product team resilient, intent-driven testing with zero per-team infrastructure overhead.  ( 149 min )
    Build a repeatable PHP-to-Java migration engine with Kiro
    Turn a PHP-to-Java migration from a one-time leap of faith into a measurable, repeatable process with Kiro. This post walks through a reusable engine: a mechanical discovery scanner and an eight-phase, parity-first workflow that treats the original PHP application as the specification and verifies the Java port with a parity harness.  ( 148 min )
    Lend and borrow resources across teams with AWS Batch’s quota management for SageMaker Training jobs
    AWS Batch quota management is a new scheduling capability you can use to divide GPU capacity into quota shares per team or project, automatically lend idle capacity across shares, and use preemption to run your highest-priority SageMaker Training jobs first, all without manual coordination.  ( 147 min )
    How MoEngage turned over 400 APIs into agent tools with AgentCore Gateway
    MoEngage turned roughly 400 private REST APIs across 7 AWS Regions into permission-scoped agent tools with Amazon Bedrock AgentCore Gateway. No per-service MCP servers, no public endpoints, and no 400-tool context bloat. See how OpenAPI specs, Cedar policies, and managed Amazon VPC Lattice egress made it work.  ( 150 min )
    Accelerate agentic AI with NVIDIA Nemotron models on Amazon EKS and SageMaker HyperPod EKS
    NVIDIA Nemotron 3.5 Super VL is a 120B-parameter mixture-of-experts model that pairs reasoning and tool use with multimodal understanding. This post explores its architecture and use cases, then shows how to deploy it on Amazon EKS, EKS Auto Mode, and Amazon SageMaker HyperPod EKS with NVIDIA Dynamo and vLLM.  ( 146 min )

  • Open

    Building an Agentic AI Platform on Amazon Bedrock AgentCore
    Stand up a governed, multi-account Agentic AI Platform on Amazon Bedrock AgentCore. This post walks through the architecture and an open-source reference blueprint: the operating model, control plane, per-Workstream cells, separate inference and tool gateways, and a CI/CD evaluation pipeline that gates each agent before production.  ( 150 min )
    Distributed training with Ray Train DLCs and EFA on EKS
    The Ray Train Deep Learning Container ships the full CUDA-through-EFA stack, so you build no image. This post walks through a reproducible sample that fine-tunes Qwen2.5-1.5B with PyTorch FSDP across eight GPUs on two EFA-enabled g6.12xlarge instances on Amazon EKS, using the container exactly as published.  ( 153 min )
    Accelerating software delivery with agentic QA automation using Amazon Nova Act – Part 3
    As QA test automation spreads across an organization, organizing tests and controlling who owns them becomes the real work. Part 3 of the QA Studio series on Amazon Nova Act adds applications that organize tests and report health metrics, plus team-based user management that controls who can see and change what.  ( 147 min )

  • Open

    AWS named a Leader in the 2026 Gartner Magic Quadrant for Contact Center as a Service
    AWS has been named a Leader in the 2026 Gartner Magic Quadrant for Contact Center as a Service (CCaaS) for AWS Connect Customer. This recognition marks an important milestone for our team, and it reflects years of work pushing on what's possible in customer experience.  ( 143 min )
    Announcing SOCI-indexed images for faster SageMaker AI jobs
    Seekable OCI (SOCI) indexing for Amazon SageMaker AI training and processing jobs takes full container image download off the critical path. SageMaker AI lazy-loads your image to start containers in seconds instead of minutes, with no changes to your job definition. See the benchmarks and how to adopt it.  ( 148 min )
    Fix evaluation bias to unlock better models on Amazon Bedrock
    Property Finder found that 96.8% of their vision-AI evaluation labels were inherited from the incumbent model, hiding its true accuracy. See how they built unbiased ground truth, applied evolutionary prompt optimization, and selected a more accurate, cost-effective model on Amazon Bedrock, cutting cost by 86% across 11 image-quality attributes.  ( 149 min )
    Exowatt beats frontier models on accuracy with SageMaker serverless model customization
    In this post, we show how Exowatt used Amazon SageMaker AI serverless model customization to build a repeatable AI pipeline that produces task-specific fine-tuned models for two deployment targets, edge and cloud, achieving higher accuracy than frontier models at up to 49x lower cost.  ( 150 min )

  • Open

    Fleet-wide computer vision lifecycle at the edge with SageMaker SDK v3
    Fleet-wide computer vision needs a model per camera, not one model for the whole fleet. This post presents a working Amazon SageMaker SDK v3 reference architecture that trains, quality-gates, compiles per-camera models with SageMaker Neo, and versions thousands of them, with an AWS Step Functions layer pacing fleet-scale retraining within account quotas.  ( 151 min )
    Groundhog Day for AI agents: Prompt caching patterns for using OpenAI models on Amazon Bedrock
    Every time an agent takes a step, it re-reads its entire context before acting. Here is how prompt caching for OpenAI models on Amazon Bedrock lets your agent remember, cutting input cost and latency without resending the same tools, instructions, and history every turn.  ( 153 min )
    Build agentic retrieval on a Managed Amazon Bedrock Knowledge Base with CDK
    Build enterprise agentic retrieval on a Managed Amazon Bedrock Knowledge Base with the AWS CDK: an agent that routes across two knowledge bases, retrieves through the AgentCore Gateway, and returns grounded, cited answers, with seven layers of observability and both on-demand and continuous evaluation, all deployed as a single CDK application.  ( 161 min )
  • Open

    SRE Weekly Issue #540
    View on sreweekly.com A message from our sponsor, Dragonfly: Redis runs one core per process. Your server has 64. Dragonfly is a Redis/Valkey-compatible data store, rebuilt multi-threaded by an ex-AWS ElastiCache engineer: 6M ops/sec on one node, no cluster Drop-in: same clients, same commands Instacart migrated and cut latency by 50% using 70% fewer nodes […]  ( 4 min )

  • Open

    Multi-Turn Reinforcement Learning on Amazon SageMaker AI: A hands-on guide
    Multi-Turn Reinforcement Learning (MTRL) on Amazon SageMaker AI trains models on the outcome of a whole multi-step task rather than labeled steps. This hands-on guide walks the full pipeline using Wordle: deploying the agent and reward on Amazon Bedrock AgentCore, preparing the dataset, training, and evaluating at serving settings.  ( 154 min )
    Orchestrating SageMaker AI endpoint auto scaling with AWS CDK
    Updating a SageMaker AI endpoint that has Application Auto Scaling registered makes AWS CloudFormation and AWS CDK deployments fail. This post shows how to build a reusable AWS CDK construct with CloudFormation custom resources that deregisters and re-registers auto scaling automatically, so you can update the endpoint and its scaling in a single deployment.  ( 147 min )
    Visualize points and routes with GeoJSON in Amazon Quick Sight layer maps
    Amazon Quick Sight layer maps now support Point and LineString geometry from the same GeoJSON workflow, so you can plot store locations and the routes between them. This post covers the dataset and GeoJSON structure layer maps require, when to choose points or lines, and techniques for viewport control, layering geometries, and dynamic GeoJSON updates.  ( 150 min )
    How Bayer Crop Science built an agentic decision engine on Amazon Bedrock AgentCore with AWS Unified Operations
    Bayer Crop Science built the Agentic Decision Engine (ADE), a multi-agent platform on Amazon Bedrock AgentCore that lets breeders, analysts, and researchers ask natural language questions about their analytics platform. This post covers the ADE architecture, five design decisions, and how the team prepared it for production with AWS Unified Operations.  ( 150 min )

  • Open

    Amazon Polly delivers a major upgrade to its Generative engine
    The Amazon Polly Generative engine gets a major upgrade: more expressive, more accurate speech with low latency, plus 14 new voices across 9 locales and general availability of Hindi and Finnish. This drop-in upgrade requires no code changes and is now generally available in production.  ( 141 min )
    How IskayPet unified corporate knowledge with Amazon Bedrock Managed Knowledge Bases
    Learn how IskayPet, a leading pet care company in Iberia, built a multilingual corporate knowledge assistant on Amazon Bedrock Managed Knowledge Bases. The assistant answers employee questions across retail, veterinary, onboarding, and procurement in four languages and three countries, with no RAG infrastructure to manage.  ( 142 min )
    Announcing new ways to customize models with SageMaker AI, without managing GPUs
    Amazon SageMaker AI serverless model customization now includes training sessions, generally available today. You write and coordinate your own post-training loop (custom loss functions, reward signals, or multi-turn reinforcement learning) while SageMaker AI handles GPU allocation, distributed execution, fault recovery, and checkpoint storage.  ( 139 min )
    Write your own training loop — without managing GPUs — with Amazon SageMaker training session APIs
    Amazon SageMaker AI training session APIs let you write your own LLM training loop (SFT, RL, or custom objectives) in a Python script while the service runs the GPUs. This post introduces the programming model and three SDK clients, then walks through a GRPO loop on GSM8K and a reinforcement learning workload on competitive programming.  ( 145 min )
    Deploy AI in a HIPAA-eligible environment with Amazon Quick
    Amazon Quick is a HIPAA-eligible service, but eligibility is not the same as compliance. This post explains who HIPAA applies to, how PHI flows through Amazon Quick, what the platform provides for regulated environments, and a step-by-step guide to deploying compliant AI agents in a healthcare environment.  ( 154 min )
    Stream low-latency speech from AI agents using Kokoro TTS on Amazon SageMaker AI
    Voice agents often wait for an agent's full response before starting speech synthesis, adding latency users feel directly. This post shows how to stream each sentence to a Kokoro-82M text-to-speech model on Amazon SageMaker AI as the agent produces it, and how to get that audio back to a browser over Server-Sent Events or a unified binary transport.  ( 145 min )
    Stop guessing auto scaling targets for TTS on Amazon SageMaker AI
    Teams deploying custom text-to-speech models on Amazon SageMaker AI often guess at autoscaling thresholds, and a wrong guess either wastes GPU spend or breaches a latency SLO. This post deploys Kokoro-82M as a custom container and derives a measured autoscaling policy from two live-endpoint measurements, Q_max and T_total, instead of guesswork.  ( 147 min )
    How Rescale built an AI triage agent with Strands Agents and AI-DLC
    Rescale used the AI-Driven Development Lifecycle (AI-DLC) framework on AWS, with Strands Agents and Amazon Bedrock, to build an intelligent test-triage agent in weeks. Learn how AI-DLC structures AI-assisted development and how Rescale is scaling the practice across its engineering organization.  ( 143 min )
  • Open

    InfoQ – eMudhra Intermediate CA Compromise
    Private keys for eight eMudhra intermediate Certificate Authority (CA) certificates have been compromised, making it trivial for attackers to forge certificates that would be trusted by unpatched roots of trust. Six of the impacted certificates were for Transport Layer Security (TLS) and trusted by the Apple, Chrome, Microsoft and Mozilla root programs. The other two […]  ( 10 min )

  • Open

    Securing Quick access from corporate networks with AWS PrivateLink
    Learn how to connect on-premises data sources to Amazon Quick privately with AWS PrivateLink, keeping analytics traffic off the public internet. This walkthrough covers VPC endpoints for user and API access, VPC connections for data sources, DNS and endpoint policies, identity federation, and enforcing VPC-endpoint-only access for compliance.  ( 154 min )
    5 production challenges in multi-agent systems and how Deep Insight solved them
    Many teams build a multi-agent AI prototype in days but hit a wall in production. This post defines five production challenges (orchestration, per-agent model selection, reliable operation, secure code execution, and monitoring) and shows how Deep Insight, an open source multi-agent system on AWS, solves each.  ( 149 min )
    Adaptive agentic intelligence framework using Strands Agents
    The Adaptive Agentic Intelligence Framework (AAIF), built with Strands Agents, handles routine tasks locally with small language models and routes complex requests to cloud models through Amazon Bedrock. This post walks through building AAIF with local SLMs through Ollama and Amazon Bedrock, using an Internet of Things monitoring scenario.  ( 142 min )
    Train Qwen3 on AWS Trainium with torchtitan
    Train Qwen3 on AWS Trainium with torchtitan three ways on a single trn2.48xlarge: the Hugging Face Transformers v5 modeling backend, torchtitan's native Qwen3, and NKI mixture-of-experts kernels. The same torchrun launcher and config structure work unchanged across all three paths, including loading and saving published Hugging Face safetensors.  ( 143 min )
    How U.S. Hunger connects leaders and data using Amazon Quick
    U.S. Hunger, a nonprofit addressing food insecurity, uses Amazon Quick to connect organizational data with leadership decisions. Leaders explore applicant data directly, share KPI definitions and financial context in Quick Spaces, and investigate policy questions with Quick Research.  ( 143 min )
  • Open

    Beyond the KV cache: Training and serving i14’s Laplace 3B linear attention model on AWS Trainium2 with native PyTorch
    Learn how i14 trained and served Laplace 3B, a linear attention model, on AWS Trainium2 using native PyTorch. Its recurrent state stays fixed at 29.5 MB per sequence regardless of context length, avoiding the growing key-value cache of transformer models and keeping serving memory predictable.  ( 145 min )
    Workflow context for AI agents with Smartsheet MCP on AWS
    The Smartsheet Model Context Protocol (MCP) Server lets AI agents read, update, and act on live data. This post shows two ways to connect it on AWS: Amazon Quick for business teams and Kiro for developers, so your agents can work with Smartsheet without switching tools.  ( 142 min )
    Work management context for AI agents with Smartsheet MCP on AWS
    The Smartsheet Model Context Protocol (MCP) Server lets AI agents read, update, and act on live work management data. This post shows two ways to connect it on AWS: Amazon Quick for business teams and Kiro for developers, so your agents can work with Smartsheet without switching tools.  ( 142 min )
    From data to decisions: Conversational supply chain intelligence with Amazon Quick and Amazon Bedrock AgentCore
    Enterprise supply chains are data-rich but insight-poor, with the data to decide scattered across ERP, monitoring, procurement, and email. This post shows how Amazon Bedrock AgentCore exposes those systems as a governed tool layer, and how Amazon Quick turns them into one conversational experience for business users, with a deploy-it-yourself walkthrough.  ( 147 min )
    Fine-tuning GPT-OSS-20B for multilingual reasoning on Amazon SageMaker HyperPod
    Learn how we fine-tuned GPT-OSS-20B for multilingual reasoning on Amazon SageMaker HyperPod, and how to decide between supervised fine-tuning (SFT) and reinforcement learning with GRPO. SFT took reasoning-language accuracy from 22% to 100%, and GRPO added measurable gains where headroom existed.  ( 144 min )
    How Octave built a secure multi-tenant AI foundation on Amazon Bedrock
    Octave built a secure, multi-tenant AI foundation on Amazon Bedrock, using Cohere Embed v4 for embeddings and Amazon Bedrock AgentCore for isolated agent execution, to power a Complaint Triage Assistant that searches 2 billion regulated documents without crossing tenant boundaries.  ( 146 min )
    Access OpenAI GPT models on Amazon Bedrock from Canada with cross-Region inference
    Canadian organizations can now access OpenAI GPT-5.6, GPT-6, and GPT-6.1 models on Amazon Bedrock from the Canada (Central) and Canada West (Calgary) Regions using cross-Region inference. This post covers the models and inference profiles, how to set up permissions, and how to invoke them with the Responses, Chat Completions, and Converse APIs.  ( 145 min )
    Discover tools at runtime with AWS Agent Registry
    Hardcoded tool wiring breaks down as an agent's catalog grows from a handful of tools to hundreds. This post walks through a runtime Discover, Instantiate, Execute loop built on AWS Agent Registry, where an orchestrator discovers MCP servers and A2A agents through semantic search at runtime instead of compiling every tool at build time.  ( 144 min )
    Securing AI agent identity with X.509 PKI on AWS
    Learn how to secure multi-agent AI systems with cryptographic identity using Keyfactor EJBCA and AWS services. This reference architecture combines signed request envelopes, user-signed delegation assertions, RFC 8693 audience-scoped tokens, and real-time OCSP revocation to prove agent identity and prevent request forgery across agent-to-agent and MCP tool calls.  ( 146 min )
    How Eon built multi-cloud investigation with an MCP Gateway on Amazon Bedrock AgentCore
    Learn how Eon replaced per-tool credentials and local MCP processes across AWS, GCP, and Azure with a single authenticated Amazon Bedrock AgentCore gateway, giving more than 100 developers and autonomous agents unified access to production investigation and cutting new-engineer onboarding from two days to two minutes.  ( 143 min )
    Build a semantic layer for agentic AI on AWS with Denodo and Amazon Bedrock AgentCore
    Build a governed semantic layer for agentic AI on AWS with the Denodo Platform and Amazon Bedrock AgentCore. It federates Amazon Aurora, Amazon Redshift, and an on-premises PostgreSQL database into a single customer 360 view an agent queries in VQL, with identity propagation and row- and column-level access control enforced at the semantic layer.  ( 156 min )
    Build a semantic layer for agentic AI on AWS with Strategy Mosaic and Amazon Bedrock AgentCore
    The third post in our semantic-layer series builds a customer 360 across Amazon Redshift and Amazon Aurora with Strategy Mosaic, exposes it to a Strands agent on Amazon Bedrock AgentCore through the Mosaic MCP server, and enforces per-user row and column security end-to-end.  ( 154 min )
    Build a semantic layer for agentic AI on AWS with AtScale and Amazon Bedrock AgentCore
    The third post in our semantic-layer series builds a governed customer 360 model on Amazon Redshift with AtScale, then exposes it to a Strands agent on Amazon Bedrock AgentCore through the AtScale MCP server. Identity propagation, RBAC, row security, and full query audit are enforced at the semantic layer, not the prompt.  ( 154 min )

  • Open

    Structured outputs for Anthropic Claude models on Amazon Bedrock
    Amazon Bedrock now supports structured outputs for all Anthropic Claude models on both the bedrock-runtime and bedrock-mantle endpoints. Receive schema-compliant JSON that conforms to a defined structure, without custom parsing, retry logic, or post-processing, using JSON Schema output format and strict tool use.  ( 142 min )
    Developers can now access SageMaker Studio through the new AWS experience
    New Amazon SageMaker AI customers can now land in a fully configured SageMaker Studio environment in only a few steps. Sign up with an identity you already have, such as Amazon, Apple, GitHub, or Google, with no advanced AWS account or credit card required for most customers, plus $100 in AWS Free Tier credits.  ( 139 min )
    Amazon SageMaker JumpStart: 2026 year-to-date in review
    Amazon SageMaker JumpStart onboarded over 100 new models from 30 providers in the first three quarters of 2026. This recap covers the model-onboarding highlights and JumpStart enhancements, including the simplified Model Hub, pre-configured deployment options, and Hugging Face deep link integration.  ( 142 min )
    Pegasus 1.5 from TwelveLabs is now available in Amazon Bedrock
    TwelveLabs Pegasus 1.5 is now available in Amazon Bedrock. The video language model turns long-form video into structured, timestamped metadata: define the moments that matter and get every matching segment back as JSON, with new video segmentation, multimodal prompting with reference images, and on-the-fly processing of up to two hours of video.  ( 146 min )
    How Deepgram optimized voice AI at scale with AWS Trainium
    Deepgram worked with the AWS Forward Deployed Engineering team to port its Nova-3 speech-to-text model to AWS Trainium2 for offline batch inference. This post covers porting to the AWS Neuron stack, kernel-level tuning, a data-parallel Rust runtime, and the throughput and cost results on batch transcription.  ( 141 min )
    Push-based KV transfer to improve TTFT and TPOT for disaggregated inference in vLLM
    vLLM's prefill-decode disaggregation splits LLM inference across engine instances but must transfer the KV cache between them. This post introduces a push-based NIXL connector that moves transfer coordination off the critical path, delivering up to 3x better TTFT and 30% better TPOT in benchmarks on Amazon EC2 P5en instances with AWS EFA.  ( 142 min )
    Improve TTFT for multi-turn agentic workloads with bi-directional KV transfer in vLLM
    Multi-turn agentic workloads reprocess growing conversation context each turn, driving up latency. See how bi-directional KV cache transfer lets prefill and decode nodes reuse previously computed context across turns, cutting time to first token by up to 1.6x for Qwen3-32B and 3.3x for GLM-5-FP8 on Amazon EC2 P5en instances with EFA.  ( 142 min )
  • Open

    SRE Weekly Issue #539
    View on sreweekly.com A message from our sponsor, Incident.io: AI made shipping code faster. Now reliability is the bottleneck. Hear how Netflix and OpenAI handle that challenge at SEV0, the reliability conference in SF and London. Free for SREWeekly readers with code SREWEEKLY. Claim your free pass → Hot take Today, I learned that “hot […]  ( 4 min )

  • Open

    Building trust in AI agents: A production-ready evaluation framework with Amazon Bedrock AgentCore
    Autonomous AI agents fail softly: latency stays flat while answer quality quietly erodes. This post shares a nine-stage evaluation framework, built on Amazon Bedrock AgentCore, that catches silent quality regressions across the full agent lifecycle, from first commit to live production.  ( 160 min )
    Introducing Reflection Beam: an open-weight model for agentic coding on AWS
    Reflection AI's Beam is an open-weight model for agentic coding and long-horizon tasks. This post shows how to deploy Beam on AWS: start with an Amazon SageMaker JumpStart real-time endpoint, or use Amazon SageMaker HyperPod Inference with JumpStart, SGLang, or vLLM for Kubernetes-native control over distributed GPU infrastructure.  ( 143 min )

  • Open

    Meta’s Muse Spark Open now available in Amazon SageMaker JumpStart
    Muse Spark Open, Meta's coding-optimized open-weight model, is now available in Amazon SageMaker JumpStart. Deploy it to a SageMaker AI endpoint in your own AWS account using SageMaker Studio or the SageMaker Python SDK, and run your first inference request.  ( 142 min )
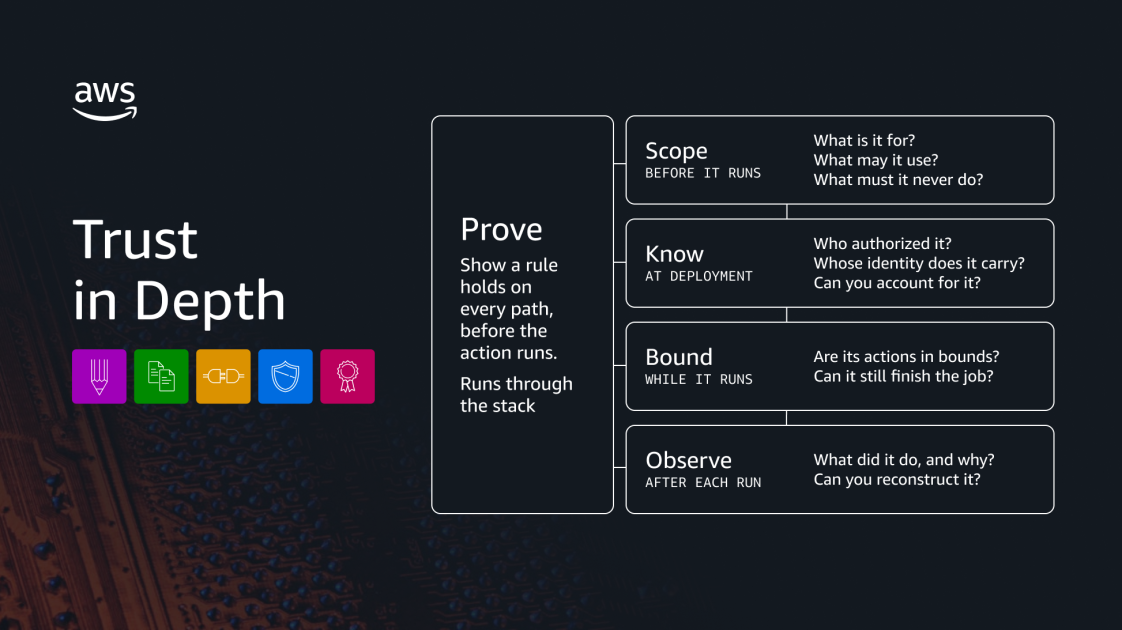
    Trust in Depth: Giving agents more autonomy without losing control
    Enterprise leaders want AI agents to take on more work but don't fully trust them to act correctly every time. Trust in Depth is AWS's layered approach-scope, know, bound, observe, and prove-that lets agents act on their own when their actions can be verified, reserving human judgment for the decisions that need it.  ( 144 min )

  • Open

    Build self-improving document processing using Amazon Bedrock AgentCore
    Learn how to build an agentic intelligent document processing (IDP) system using Amazon Bedrock AgentCore that classifies, extracts, validates, and learns from business documents with minimal human intervention, automatically handling new document formats without manual template configuration.  ( 144 min )
    Generate presentations with Amazon Bedrock AgentCore
    This post walks you through building an AI agent system with Amazon Bedrock AgentCore that automates PowerPoint presentation creation from enterprise documents. A supervisor agent, Retrieval Augmented Generation, and Amazon Bedrock Guardrails generate grounded presentations in under 90 seconds.  ( 143 min )
    How Tamnoon built AI-powered cloud security remediation with Amazon Bedrock
    Learn how Tamnoon built Tami, an agentic cloud remediation orchestrator on Amazon Bedrock that autonomously investigates and safely remediates cloud security findings from CNAPP and cloud-native sources. The approach drove a 90%+ reduction in critical cloud exposure in 90 days with zero production issues.  ( 145 min )
    Deploy and evaluate models with Amazon SageMaker JumpStart
    Learn how to deploy an available model from Amazon SageMaker JumpStart, run a lightweight and repeatable performance test using the SageMaker Python SDK, and delete the endpoint when testing is complete.  ( 140 min )

  • Open

    Building agents that transact with Anchor Browser and AgentCore payments
    Learn how the AWS Generative AI Innovation Center Partner Agent Factory and Anchor Browser built AI agents that autonomously pay for x402-protected web resources and APIs. Amazon Bedrock AgentCore payments checks budgets, signs transactions, and retries requests without exposing wallet credentials to the agent runtime.  ( 144 min )
    Manage private pricing offers for Amazon Bedrock with managed entitlements
    Managing AI model access across dozens or hundreds of AWS accounts creates friction when each account must accept AWS Marketplace Private Pricing Offers individually. This post shows two ways to activate MPPO entitlements in AWS License Manager: a lightweight script for a one-time fix, and CDK automation for ongoing event-driven processing.  ( 140 min )
    Natural language security queries at Orca Security using Amazon Bedrock
    Orca Security built Discovery AI, a natural language query agent on Amazon Bedrock that converts plain-English questions into Sonar queries. The post shares the multi-stage architecture and the results: 90% lower query cost, 93% fewer input tokens, and 75% lower latency than the initial baseline.  ( 143 min )
    How ShipStation Global built an AI IT help desk on Amazon Bedrock AgentCore
    ShipStation Global's engineering team built Deckhand, an AI IT help desk agent for Slack on Amazon Bedrock AgentCore. It answers routine IT questions from a curated knowledge base, reads error-message screenshots, and files Jira tickets. In its first three months it resolved 97.5% of channel queries with a 96% positive feedback rating.  ( 144 min )
    Build long-horizon agents with Grok 4.7 on Amazon Bedrock
    Grok 4.7 is now available on Amazon Bedrock. In this post, we build a tool-calling agent on Grok 4.7 and evaluate it on three reasoning tasks at four reasoning effort levels, measuring correctness and token cost per completed task. We show how to tune the trade-off per request and monitor it in production.  ( 147 min )
    Mixture-of-Experts kernel engineering on Amazon SageMaker AI
    AWS engineers share kernel optimizations for fused Mixture-of-Experts (MoE) models on Amazon SageMaker AI: Swap-AB for WGMMA utilization, Triton backend routing for FP8 quantization, and eliminating Triton JIT recompilation. Together they deliver up to 10% higher throughput and up to 9% faster Time to First Token on H200 GPUs.  ( 141 min )

  • Open

    Accessing OpenAI GPT models on Amazon Bedrock with global cross-Region inference in Thailand, Malaysia, Singapore, Indonesia, and Taiwan
    Learn how to run OpenAI GPT-6 Sol, Luna, and Astra on Amazon Bedrock through global cross-Region inference from Singapore, Jakarta, Thailand, Malaysia, and Taipei. This post covers the Converse and OpenAI-compatible APIs, IAM and SCP permissions, quota sizing, and monitoring inference from your source Region.  ( 145 min )
    Deploy decision models with llama.cpp on Amazon SageMaker AI
    Learn how to deploy decision models with llama.cpp on Amazon SageMaker AI. This technical how-to serves OpenAI-compatible chat completions with the AWS Deep Learning Container for llama.cpp, then extends the runtime with SemIf to return probabilities over declared options on CPU or GPU.  ( 143 min )
    Run multi-node inference workloads using Ray LLM Deep Learning Containers
    Learn how to deploy one large language model across two GPU nodes on Amazon EKS using the multi-node Ray LLM Deep Learning Containers, with separate prefill and decode nodes behind one OpenAI-compatible endpoint. The pre-built container ships the full inference stack, so you configure the deployment instead of assembling it.  ( 143 min )
  • Open

    SRE Weekly Issue #538
    View on sreweekly.com A message from our sponsor, Antithesis: Author and CTO community leader Peter Bell offers engineering leaders a clear, pragmatic framework for adopting and scaling AI across the entire software development lifecycle. Read now: Scaling AI Adoption in Engineering (Early Release) Building Investigations: what it takes to build an AI SRE This is […]  ( 4 min )

  • Open

    September 2026
    Pupdate The heat wave(s) finally let up, but much of the month was still warm and sunny, allowing for some good walks. As I covered in an earlier post, Milo’s back in remission :) Caskmaster The Scotch Malt Whisky Society (SMWS) has started running a tasting competition called Caskmaster, with heats in various tasting rooms […]  ( 12 min )

  • Open

    ICYMI: What landed for AI builders in September 2026
    A monthly recap of the latest Amazon Bedrock, Amazon Bedrock AgentCore, and Strands updates from September 2026: broader model choice, faster serverless agents with built-in evaluation, and automated knowledge base syncing with native enterprise connectors.  ( 139 min )
    How Postman runs Agent Mode for 40 million developers on Amazon Bedrock
    Building an AI agent that works in a demo is a different problem from running one for 40 million developers. Postman and AWS share the architectural patterns behind Agent Mode: controlling tool sprawl, exposing schema-based reads, and treating context as the real bottleneck, plus how it runs on Amazon Bedrock at scale.  ( 144 min )

  • Open

    Pay-per-inference for AI agents: How BlockRun and Incarna use Amazon Bedrock AgentCore payments
    Amazon Bedrock AgentCore payments gives AI agents a managed way to pay for services on demand, with spending limits enforced by the infrastructure. See how Incarna's agents pay BlockRun for model inference one request at a time over x402, cutting the work of adding x402 payment support from months to days.  ( 128 min )
    Share GPU clusters across teams with isolation and fairness using Amazon SageMaker HyperPod
    A reference architecture for securely sharing one Amazon SageMaker HyperPod EKS cluster across multiple teams, using AWS IAM Identity Center for authentication, per-team SageMaker Domains and Kubernetes namespaces for isolation, HyperPod Task Governance for fairness, and namespace-level cost allocation for chargeback.  ( 143 min )

  • Open

    Introducing Claude Haiku 5.5 on AWS
    Claude Haiku 5.5 is now available on Amazon Bedrock and Claude Platform on AWS. According to Anthropic, it is the fastest, most efficient model in the Claude 5.5 family, built for subagents and high-volume, cost-sensitive work, and costs around 75% less than Claude Haiku 4.5 for most tasks. This post covers its improvements and how to get started.  ( 126 min )
    Rethinking access control for RAG with Amazon Quick and Amazon Bedrock
    Enterprise RAG unlocks insights from knowledge sources like SharePoint, Google Drive, and Confluence, but those sources carry complex permissions. Learn how Amazon Quick and Amazon Bedrock Knowledge Bases enforce document-level access controls in real time, verifying permissions directly with authoritative sources at query time.  ( 126 min )
    Beyond hours saved: Building the business case for agentic automation
    The RPA-era ROI model misses most of the value agentic automation creates. This post gives AI center of excellence leaders a framework to size the full value of agents across time savings, exception handling, decision quality, and maintenance economics, and to prioritize which workflows to automate first.  ( 129 min )
    How Qlik built grounded, enterprise-scale AI with Amazon Bedrock
    Qlik built Qlik Answers on Amazon Bedrock to give its 40,000+ customers grounded, sourced answers across structured and unstructured enterprise data. Learn how a layered, multi-agent architecture with cross-Region inference and Amazon Bedrock Guardrails delivers trusted AI at global scale.  ( 129 min )
    Automate remediation post AWS DevOps Agent investigation
    AWS DevOps Agent can diagnose production incidents but is kept in observe-and-report mode so it does not change resources directly. This post shows how to use AWS Lambda Durable Functions, Amazon EventBridge, and Amazon Bedrock to turn its investigation summaries into pre-validated fixes an on-call engineer can approve with a single action.  ( 130 min )
    Building AI builders: Playbook for closing the AI knowledge-capability gap
    The biggest barrier to AI adoption isn't awareness. It's the gap between talking about AI and building with it. Here's the playbook we used to turn non-technical, customer-facing professionals into confident AI builders in six weeks, and how your organization can replicate it.  ( 130 min )
    How Cornerstone OnDemand cut database diagnosis by 78% with Amazon Bedrock
    Cornerstone OnDemand built Orion AI, a multi-agent system on Amazon Bedrock and Strands Agents, to turn database operations from reactive firefighting into proactive automation. A three-person team cut database diagnosis from 45 minutes to 10, a 78% reduction, in six months. See the design decisions other teams can reuse.  ( 129 min )

  • Open

    Building a context-aware AI assistant on AgentCore and OpenClaw
    Off-the-shelf AI assistants forget you between conversations. This post shows how to build a personal assistant that accumulates context using OpenClaw on Amazon Bedrock AgentCore runtime, with AgentCore memory turning disposable chats into durable, structured knowledge you can retrieve with metadata filters.  ( 133 min )
    Responsible AI governance: How AWS positions customers to align with ISO/IEC 42005:2025
    AWS invests in tools that help customers align with international standards for responsible AI governance. In this post, we explore the AI system impact assessment: what it is, how it improves enterprise-wide risk management, and how ISO/IEC 42005:2025 codifies best practices for conducting and documenting these assessments.  ( 127 min )
    Best practices for Amazon SageMaker HyperPod administration and governance
    Learn how to administer Amazon SageMaker HyperPod through Amazon SageMaker Unified Studio while preserving cluster governance. This post shows platform teams how to design infrastructure boundaries, govern access, allocate shared capacity, and operate HyperPod consistently across the organization, project, cluster, and workload control layers.  ( 132 min )
    Manage Amazon SageMaker HyperPod Spaces directly from SageMaker Studio
    Data scientists and ML engineers can now create, configure, start, stop, and open Amazon SageMaker Spaces on SageMaker HyperPod EKS clusters directly from SageMaker Studio. Launch JupyterLab and Code Editor environments in a few clicks, without using command-line tools.  ( 129 min )
    Build a voice travel concierge with Amazon Bedrock AgentCore, Managed Knowledge Base and Nova Sonic
    Add a voice travel concierge to an airline app with Amazon Bedrock AgentCore, Amazon Nova Sonic for real-time speech, and Amazon Bedrock Knowledge Bases for policy answers. Travelers change seats, check delays, and ask policy questions by voice, while the agent reaches your backend through MCP tools and confirms every change before it writes.  ( 132 min )

  • Open

    Introducing GLM 5.3 on Amazon Bedrock
    GLM 5.3 from Z.ai is now available on Amazon Bedrock: a 753B-parameter mixture-of-experts model built for coding and long-horizon agentic tasks. Learn how to invoke it with the OpenAI-compatible APIs, cut cost and latency with prompt caching, and run an authorized security test with the open-source Strix agent.  ( 128 min )
    Supercharge regulated workloads with Claude Code and Amazon Bedrock
    Anthropic Claude Opus 5.5 and Claude Sonnet 5.5 are available on Amazon Bedrock in the AWS GovCloud (US) Regions. Learn how to use them with Claude Code, Anthropic's agentic coding tool, for compliance-aligned, AI-assisted development on regulated and ITAR workloads.  ( 130 min )
    New agent skill: Amazon SageMaker optimized generative AI inference for your coding agent
    Amazon SageMaker optimized generative AI inference introduces the aws-ai-ml skill through the Agent Toolkit for AWS, giving coding agents like Kiro, Claude Code, and Codex deep expertise in inference optimization and benchmarking. Describe what you want, and your agent generates executable SageMaker Python SDK v3 code to benchmark, recommend, and compare deployments.  ( 129 min )
    Making Amazon Quick enterprise-ready: Automated, auditable cross-account resource promotion
    Promoting Amazon Quick resources (agents, action connectors, knowledge bases, flows, and spaces) from a development to a production AWS account has been a manual, error-prone chore. This post shows how to automate cross-account promotion with an idempotent, auditable MCP server on Amazon Bedrock AgentCore.  ( 130 min )
    Agentic retrieval with LangChain and Amazon Bedrock Knowledge Bases
    Build a Retrieval Augmented Generation (RAG) application on Amazon Bedrock Managed Knowledge Base with LangChain, and see how agentic retrieval handles the multi-part questions that single-shot retrieval answers poorly. Run the same query through both paths, read the trace events, and compare what each retrieval path costs.  ( 132 min )
    Downgrading user roles in Amazon Quick
    Amazon Quick doesn't offer a direct console path to downgrade a user from Admin or Author to Reader. This post walks through two reliable methods: a manual delete-and-recreate approach and an AWS CLI step-down sequence that downgrades roles safely while preserving asset ownership.  ( 130 min )
    Evaluating multi-agent systems for explainability and helpfulness with Amazon Bedrock AgentCore
    Multi-agent systems need deeper guarantees than fluent responses: they must select the right tools, respect constraints, and explain their decisions. Learn how to build a Strands-based multi-agent supply chain decisioning system and evaluate it with Amazon Bedrock AgentCore Evaluations using built-in, custom, and explainability evaluators.  ( 132 min )
  • Open

    SRE Weekly Issue #537
    View on sreweekly.com A message from our sponsor, WarpBuild: WarpBuild runs your GitHub Actions jobs on runners that are 2x faster at half the cost. Change one line in your workflow file and keep everything else. Get $50 in free credits to try it now Try WarpBuild free Can Claude fix itself? From no to […]  ( 4 min )

  • Open

    我做了一个 AI 图片重命名工具
    我做了一个 AI 图片重命名工具:看懂照片内容,再生成有意义的文件名 整理旅行照片时,我经常遇到一个问题:相机和手机生成的文件名通常是 IMG_8428.JPG IMG_0698.JPG 这样的编号。 当照片数量较少时,还可以逐张打开查看;但一次旅行拍摄几十甚至几百张照片后,仅凭文件名几乎无法知道照片内容。想找到“国清寺古建筑”“天台山瀑布合影”或者“琼台仙谷悬索桥”,只能不断翻看缩略图。 为了解决这个问题,我开发了一个带图形界面的 Python 工具:AI 照片与视频重命名器。 它可以调用本地视觉模型识别照片内容,自动生成类似下面这样的文件名: IMG_0506.JPG → 20260812-天台山大瀑布景区-一家三口合影.JPG IMG_8428.JPG → 20260813-国清寺-黄墙古树与石狮.JPG IMG_8422.JPG → 20260812-琼台仙谷-悬索桥近景.JPG 相比没有含义的相机编号,这样的名称更容易搜索、归档和长期保存。 视频演示 your browser does not support the HTML5 Video element 这个工具能做什么? 工具使用 Python 和 Tkinter 开发,提供了一个轻量的桌面操作界面。用户不需要编写命令,只需要选择媒体目录、配置模型,然后按照“扫描—分析—预览—确认”的流程操作。 目前支持以下功能: 选择指定的图片或视频目录 可选择是否递归扫描子目录 支持 JPG、JPEG、PNG、WebP 和 BMP 图片 支持 MOV、MP4、M4V、AVI 和 MKV 视频 在界面或 .env 中配置接口类型、模型、API 地址和可选 API Key 支持 Ollama 原生接口:/api/chat 和 /api/tags 支持 OpenAI 兼容接口:/v1/chat/completions 和 /v1/models 自动生成带日期和场景描述的文件名 重命名前预览全部结果 支持手工修改 AI 生成的名称 自动清理 Windows 文件名中的非法字符 自动处理同名文件并添加序号 不覆盖目录中已经存在的文件 批量重命名失败时尝试回滚 整个过程只会修改文件名,不会修改图片、视频内容或照片中的 EXIF 信息。 为什么支持本地视觉模型? 这款工具默认可以连接本机运行的 Ollama 服务。当前也支持通过 LLM_API_TYPE 切换到 OpenAI 兼容接口: # Ollama 原生接口 LLM_API_TYPE=ollama LLM_MODEL=qwen3.8:27b LLM_API_HOST=http://127.0.0.1:11434 LLM_API_KEY= 如果使用 OpenAI 兼容服务,可以这样配置: LLM_API_TYPE=openai LLM_MODEL=你的视觉模型 LLM_API_HOST=https://你的服务地址/v1 LLM_API_KEY=你的密钥 LLM_API_TYPE 只有两个取值:ollama 和 openai,默认是 ollama。OpenAI 模式会请求标准的 /v1/chat/completions 接口,并将压缩后的图片作为视觉输入发送;如果地址已经以 /v1 结尾,程序不会重复追加路径。 1. 本地模型可以减少隐私顾虑 当 API 地址配置为 127.0.0.1 或其他本机回环地址时,图片分析请求只发送给本机运行的模型服务。家庭照片、旅行合影等内容不需要上传到外部云平台。 如果配置的是远程 Ollama 或 OpenAI 兼容服务,图片仍然会发送到该服务。因此,使用前应确认服务的隐私政策、数据处理方式和访问控制;远程 HTTP 地址也应改用 HTTPS。 2. 模型可以自由切换 模型名称、接口类型和 API 地址都可以在 .env 文件或图形界面中配置。OpenAI 兼容服务如果需要鉴权,可以填写 LLM_API_KEY,本地不需要鉴权的服务则可以留空。 需要注意的是,所选模型必须支持视觉输入。纯文本模型无法识别照片内容。 图片和视频是怎样处理的? 直接把数 MB 甚至十几 MB 的原图发送给模型,会占用较多内存和视觉 Token。为此,程序会先对图片进行预处理: 读取并修正照片的 EXIF 方向; 将图片最长边缩小到 1280 像素; 转换为适合模型分析的 JPEG 数据; 根据接口类型生成请求:Ollama 使用 images 字段,OpenAI 兼容接口使用 data:image/jpeg;base64,... 的 image_url; 解析模型返回的文件名描述,并清理 Windows 不允许的字符。 这个过程只在内存中生成缩略图,不会修改原始照片。 对于视频,程序会通过 FFmpeg 获取视频时长,抽取中间位置的一帧,然后让视觉模型根据这一帧生成名称。临时画面会在分析结束后自动删除。 这种方案无法概括长视频的全部内容,但对于手机拍摄的短视频、Live Photo 片段和旅行记录,通常已经能够提供有意义的名称。 为什么不让 AI 直接修改文件? AI 生成的名称并不一定每次都完全准确。例如,它可能无法确定具体景点,或者把人物关系描述得过于笼统。 因此,这个工具没有采用“分析后立即重命名”的方式,而是加入了一个预览确认流程: 扫描目录中的媒体文件; AI 逐个分析并生成建议名称; 用户检查全部结果; 对不满意的名称进行手工修改; 最后统一确认并应用。 只有用户点击“应用重命名”并再次确认后,程序才会真正修改文件名。 文件安全方面做了哪些处理? 批量重命名看起来简单,但需要考虑文件重名、非法字符和中途失败等情况。 程序会自动清理 Windows 不允许出现在文件名中的字符: < > : " / \ | ? * 如果多个文件得到相同的名称,程序会自动添加序号: 天台山大瀑布-瀑布近景.JPG 天台山大瀑布-瀑布近景-02.JPG 天台山大瀑布-瀑布近景-03.JPG 正式重命名前,程序还会检查目标文件是否已经存在,避免覆盖原有文件。 批量操作采用两阶段重命名:文件首先被改成唯一的临时名称,确认全部进入临时状态后,再转换成最终名称。如果过程中发生异常,程序会尽可能恢复原始文件名。 安装和运行 项目使用独立的 Python 虚拟环境,不会把依赖安装到系统 Python 中。 进入项目目录后运行: powershell -ExecutionPolicy Bypass -File .\setup.ps1 安装脚本会自动: 创建 .venv; 安装锁定版本的 Python 依赖; 在缺少 .env 时从模板创建配置文件。 然后编辑 .env。继续使用 Ollama 时: LLM_API_TYPE=ollama LLM_MODEL=qwen3.8:27b LLM_API_HOST=http://127.0.0.1:11434 LLM_API_KEY= 切换到 OpenAI 兼容接口时: LLM_API_TYPE=openai LLM_MODEL=你的视觉模型 LLM_API_HOST=https://你的服务地址/v1 LLM_API_KEY=你的密钥 系统环境变量优先于 .env,程序界面中的修改只对当前运行生效。.env 不应提交到 Git 仓库,API Key 也不要写入公开配置或博客。 启动程序: powershell -ExecutionPolicy Bypass -File .\run.ps1 run.ps1 会始终使用项目目录下 .venv 中的 Python。如果虚拟环境不存在,它会先自动执行安装脚本。 使用流程 实际操作只需要几步: 点击“选择目录”,指定待处理的照片或视频目录; 选择接口类型:ollama 或 openai; 配置 API 地址、视觉模型,以及需要时填写 API Key; 点击“测试连接”,确认服务可访问且模型名称正确; 点击“扫描目录”; 点击“AI 分析全部”; 检查并手工修改建议名称; 点击“应用重命名”,确认后完成批量处理。 分析过程采用顺序处理,不会同时把大量原图加载到内存中,更适合包含几十或几百个媒体文件的目录。正式重命名之前,所有建议都可以在表格中检查和修改。 当前版本的局限 目前版本仍有一些可以继续改进的地方: 日期前缀暂时来自文件修改时间,还没有优先读取 EXIF 拍摄时间; 视频只分析中间一帧,无法完整理解长视频内容; 景点识别依赖视觉模型自身能力,模型可能只能描述画面而无法判断准确地点; AI 生成的名称仍建议在应用前人工检查; 不同 OpenAI 兼容服务对视觉消息格式和模型名称的支持程度可能存在差异。 未来可以继续增加 EXIF 拍摄时间、地理位置、多个视频关键帧、命名模板以及重复照片检测等功能。 项目源码 完整源码和安装说明已发布在 GitHub: 查看 GitHub 项目源码 如果你也有大量使用 IMG_XXXX.JPG 命名的旅行照片,希望这个工具能帮助你更高效地完成整理。  ( 1 min )

  • Open

    Sweep thousands of leases for compliance using Amazon Quick and the Adjudicated Query pattern
    The Adjudicated Query pattern pairs the Amazon Quick chat agent with a bounded MCP server over a deterministic rules engine to deliver provably complete, defensible compliance answers. This post walks through the reference architecture and a deployable AWS CDK sample, using lease compliance as the running example.  ( 135 min )
    Add secure Web Search to Claude Desktop with Amazon Bedrock AgentCore
    Claude Desktop on Amazon Bedrock is limited to the model's knowledge cutoff without web search. In this post, we walk through connecting Claude Desktop to Web Search using Amazon Bedrock AgentCore Gateway, with JWT-based inbound authentication through AWS IAM Identity Center and Amazon Cognito.  ( 129 min )
    Fine-tune a search agent with multi-turn RL on Amazon SageMaker AI
    Fine-tuning teaches a small search agent your tools and environment, giving it the reliability of a frontier model at lower latency and cost. In this post, we fine-tune an LLM-powered search agent with multi-turn reinforcement learning (MTRL) on Amazon SageMaker AI and share the gains we measured in retrieval quality and reliability.  ( 129 min )
2026-10-31T14:27:01.087Z osmosfeed 1.15.1